Abacus Hardware

NVIDIA AI Compute Solutions

Enterprise NVIDIA GPU Accelerators — Skip Long Waiting Times

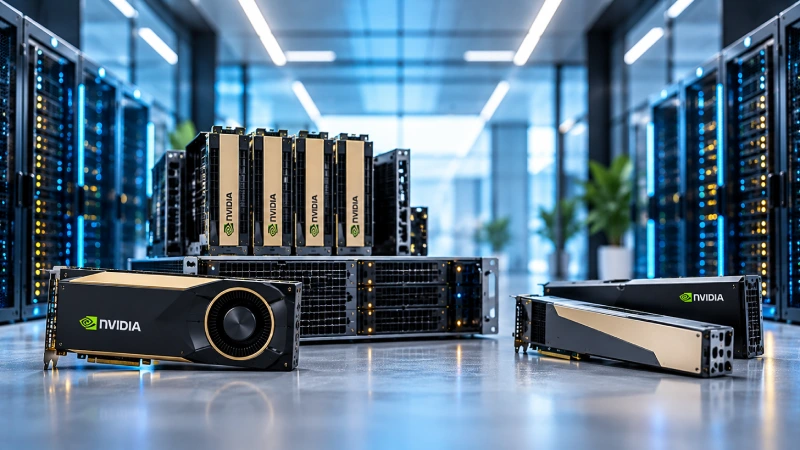
Eliminate 20+ week OEM factory queues. Abacus Hardware supplies new as well as certified refurbished, enterprise-grade NVIDIA GPU architectures—from HGX A100 and H100 clusters to L40S and PCIe cards—delivering maximum compute density for LLM training, massive parameter fine-tuning, and real-time inference engines.

Fully Burn-In Tested

NVLink/NVSwitch Recertified

3-Year Warranty Included

Fully Burn-In Tested

NVLink/NVSwitch Recertified

3-Year Warranty Included
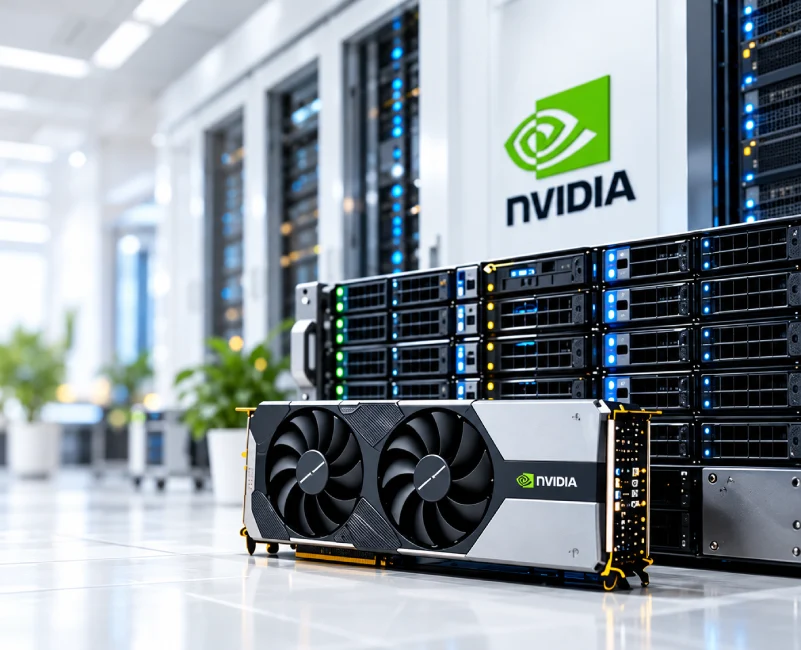
NVIDIA AI Compute Solutions

Enterprise NVIDIA GPU Accelerators — Skip Long Waiting Times

Eliminate 20+ week OEM factory queues. Abacus Hardware supplies new as well as certified refurbished, enterprise-grade NVIDIA GPU architectures—from HGX A100 and H100 clusters to L40S and PCIe cards—delivering maximum compute density for LLM training, massive parameter fine-tuning, and real-time inference engines.

Fully Burn-In Tested

NVLink/NVSwitch Recertified

3-Year Warranty Included

Fully Burn-In Tested

NVLink/NVSwitch Recertified

3-Year Warranty Included

Social Proof & Architecture Coverage

Trusted Data Center Accelerators Across All Generations

We stock and recertify full-stack NVIDIA hardware to maintain continuous supply chains for AI startups, cloud providers, and enterprise data centers.

Deployment Footprint:

10,000+ NVIDIA Cards Shipped

Zero-Downtime Stress Certified
Deployment Footprint:

10,000+ NVIDIA Cards Shipped

Zero-Downtime Stress Certified

Supported GPU Generations:

Blackwell

Architecture (B200)

Hopper

Architecture (H100, H200)
Ampere

Architecture (A100, A30)
Ada Lovelace

(L40S, L4)
Volta

(V100)
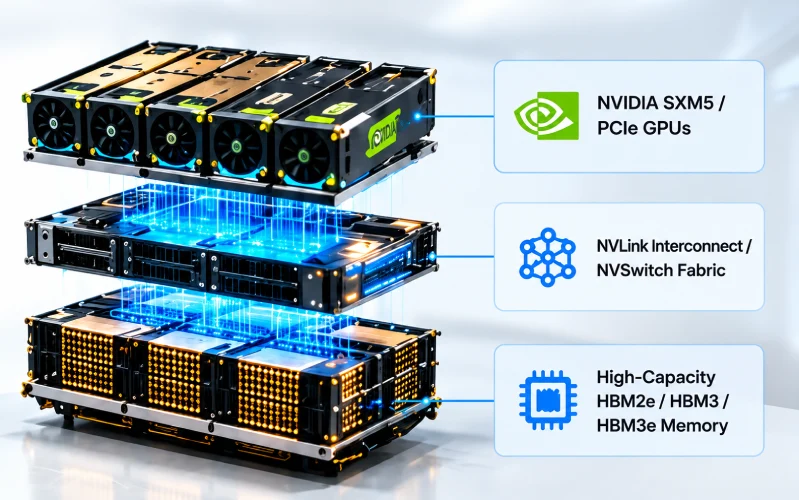
Core Compute & Architecture Deep Dive

Accelerated Tensor Core Technology for Complex AI Workloads

Scale parallel processing efficiency using verified NVIDIA compute cards. We stress-test individual GPU modules, high-speed NVLink interconnects, and cooling arrays under maximum compute stress before dispatch.
Core Compute & Architecture Deep Dive

High-Bandwidth Memory (HBM3/HBM3e)

Prevent processing bottlenecks in billion-parameter models. High-capacity HBM architectures keep multi-modal training sets and large language models localized on-chip for ultra-low latency execution.

NVLink & NVSwitch Interconnect Fabric

Achieve seamless GPU-to-GPU communication at up to 900 GB/s bidirectional bandwidth per card. High-speed interconnect fabrics enable unified memory access across multi-node server clusters.

Transformer Engine & Tensor Cores

Optimize mixed-precision FP8, FP16, and INT8 computational pipelines. Integrated Transformer Engines dynamically manage precision modes to double processing speed without sacrificing output accuracy.

Enterprise PCIe & SXM Form Factors

Deploy flexible hardware nodes across custom rack geometries. Choose SXM architectures for dense, multi-GPU clusters or PCIe form factors for drop-in workstation upgrades.

GPU Model Breakdown & Workload Matrix

Targeted Hardware for Your AI Stack

GPU Model Form Factor VRAM / Memory Type Primary Workload Focus
NVIDIA H100 SXM5 / PCIe 80GB HBM3 Large Language Model (LLM) Pre-training, Massive Multi-Node Clusters
NVIDIA A100 SXM4 / PCIe 40GB / 80GB HBM2e Enterprise Model Fine-Tuning, Deep Learning, High-Performance Computing
NVIDIA L40S PCIe 48GB GDDR6 Generative AI, High-Throughput Inference, Computer Vision, 3D Rendering
NVIDIA A30 / L4 PCIe 24GB HBM2 / GDDR6 Cost-Effective Edge Inference, Model Prototyping, Mainstream AI Workloads

Industry Use Cases

Proven Acceleration for Sector-Specific Pipelines

AI is becoming part of everyday workflows across technical, creative and operational teams. Abacus Hardware supplies systems that can be aligned with the performance, reliability and deployment needs of different sectors.

LLM Development

LLM Development

Dense SXM HGX H100 / A100 Clusters
Generative Media

Generative Media

L40S Parallel Processing Arrays
Algorithmic Finance

Algorithmic Finance

Low-Latency PCIe Accelerators
Edge Vision Systems

Edge Vision Systems

L4 & A30 Compact Compute Nodes

Generative AI & LLMs

Train, fine-tune, and serve foundational models with zero compute bottlenecks.

Computer Vision & VFX

Render complex spatial environments and run real-time video analytics engines.

Quantitative Finance

Execute low-latency risk simulations, predictive forecasting, and automated market models.

Healthcare & Life Sciences

Speed up genomic mapping, molecular dynamics, and advanced medical image diagnostics.

Testing, Quality & Circular Economy

Factory-Grade Validation for Refurbished Accelerators

100% Thermal & Stress Burn-In Diagnostics

Every NVIDIA GPU passes diagnostic cycles including CUDA stress tests, thermal throttling verifications, and memory bit-error checks under sustained 100% load.

Cost Efficiency Meets ESG Leadership

Save up to 50% compared to new hardware MSRP while extending high-efficiency silicon life cycles. Slash Scope 3 emissions without sacrificing raw processing capacity.
Frequently Asked Questions

Absolutly. NVLink bridges, SXM baseboards, and NVSwitch links undergo multi-gpu communication stress tests prior to packaging.

Yes. We maintain active inventory of certified pre-owned, OEM-surplus, and refurbished Hopper and Ampere generation cards ready for dispatch.

NVIDIA FAQ
Secure Your NVIDIA Compute Capacity Today

Secure Your NVIDIA Compute Capacity Today

Skip long lead times and scale your GPU clusters immediately with certified new and refurbished NVIDIA hardware.